Selenium - Easy Web Automation with Python.
TL;DR: Selenium lets you control a browser programmatically with Python, turning multi-step manual tasks into a single command. This post demonstrates automating an everyday task -- opening an online epaper that normally requires opening the browser, searching, clicking through pages, and zooming. With Selenium and a chromedriver, you script the entire flow. The walkthrough covers setup, element selection, clicking, and handling browser interactions.
I went through a course on udemy ( Automate boring stuff with python ) back in 2018, from there I got that we can automate many tasks from daily life.
What is Selenium?
Selenium is widely used in writing automated tests for web-applications. Selenium lets you run an automated instance of web browser( chrome, firefox ), and gives you APIs so you can control the browser and webpage.
"Selenium automates browsers. That's it!" — selenium.dev
Version note: the code below was written for Selenium 3. Since Selenium 4.6, Selenium Manager downloads the right browser driver for you, and the executable_path argument was removed in Selenium 4.10. On a current version, webdriver.Firefox() with no arguments is enough.
How can Selenium automate a daily task?
Lets take a simple example of reading an online epaper. Steps to get to last point are,
- Open the browser.
- Go to the epaper website ( readwhere.com in my case ).
- Search for the newspaper name.
- Click on "Read Now".
- Skip sign in.
- Maximize/zoom for better reading.
Doing this could easily take 3-5 minutes. With selenium we can sum it up to a single command.
Code walkthrough
- I have taken a link to the newspaper name directly so we do not have to search for the newspaper.
url = 'https://www.readwhere.com/newspaper/deshonnati/Akola-Main/557?refquery=deshonnati%20akola'
- Below snippet opens up a browser instance, you need to pass corresponding driver ( chrome-chromedriver, firefox-gecodriver )
browser = webdriver.Firefox(
  executable_path=r'/usr/local/bin/geckodriver')
- In next step, we provide this browser which url it should load.
browser.get(url) # URL of newspaper
browser.maximize_window()
- Then we tell browser to perform certain clicks.
With
WebDriverWaitwe tell browser to wait until the element appears on the screen and is clickable(EC.element_to_be_clickable). We search the element by its DOM path called XPath (By.XPATH), and then perform a click.
# Click on "READ NOW"
WebDriverWait(browser, 6).until(EC.element_to_be_clickable(
        (By.XPATH, '/html/body/div[4]/div/div/div[3]/div/div[2]/div[1]/div[3]/a'))).click()
# Click on "Skip Sign in"
WebDriverWait(browser, 6).until(EC.element_to_be_clickable(
        (By.XPATH, '//*[@id="skip-area-id"]'))).click()
# Click on "Zoom + button"
WebDriverWait(browser, 6).until(EC.element_to_be_clickable(
        (By.XPATH, '/html/body/div[7]/div[1]/div[1]/div[4]/div/button[1]'))).click()
Common problems and fixes
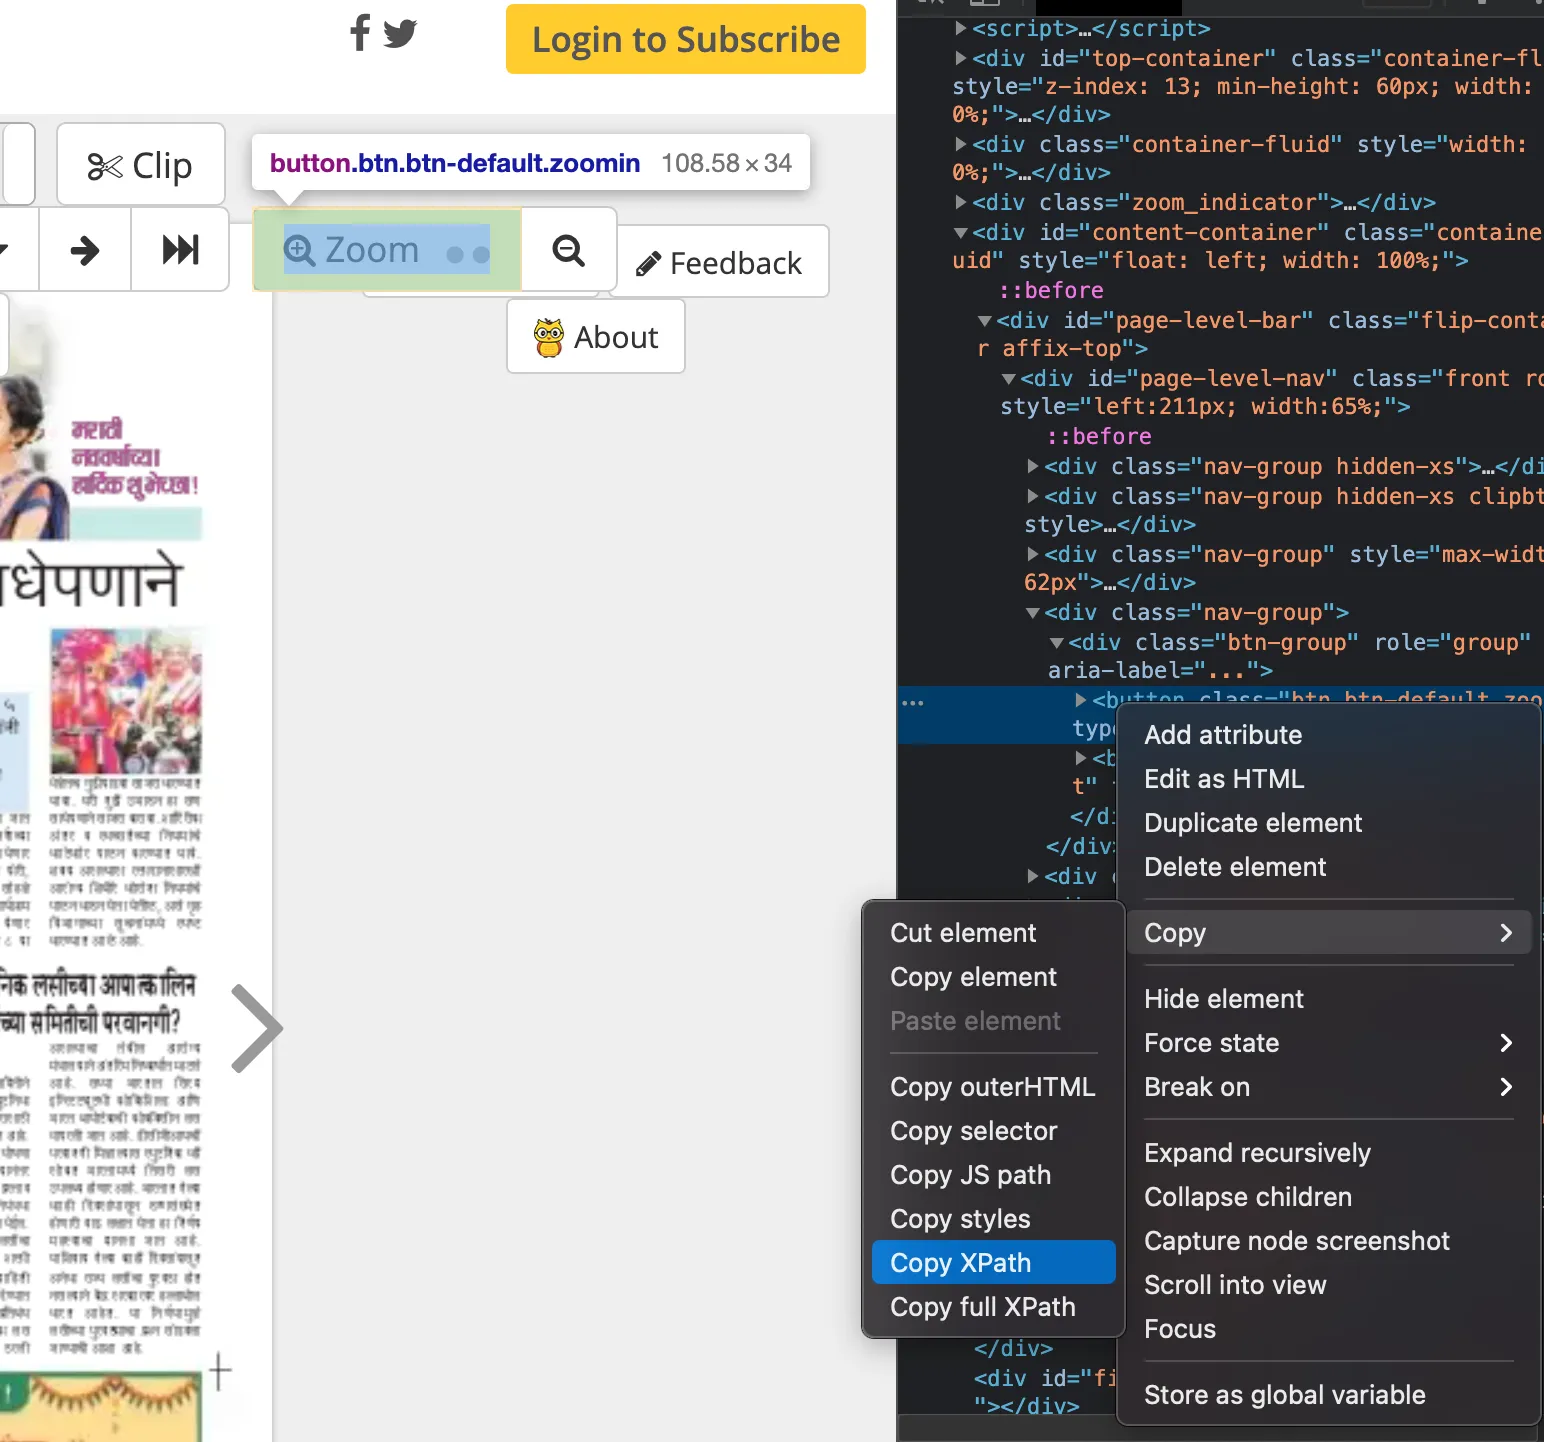
How to find xpath of the browser element.
- Right click on the element, select
inspect element. - In the elements tab right click on the element and select
copy, then selectCopy XPath
Run the browser in headless ( invisible ) mode.
options = Options()
options.headless = True
browser = webdriver.Firefox(options=options,
   executable_path=r'/usr/local/bin/geckodriver')
End Result
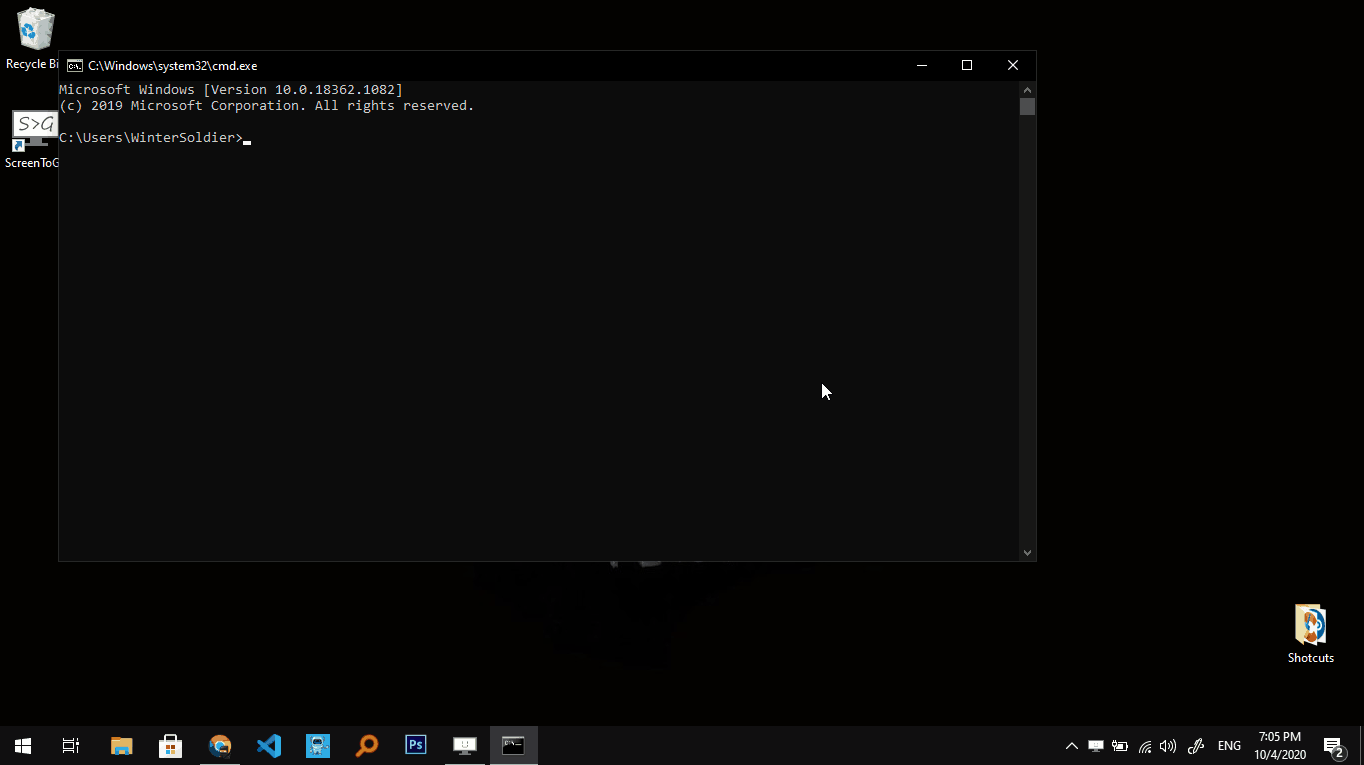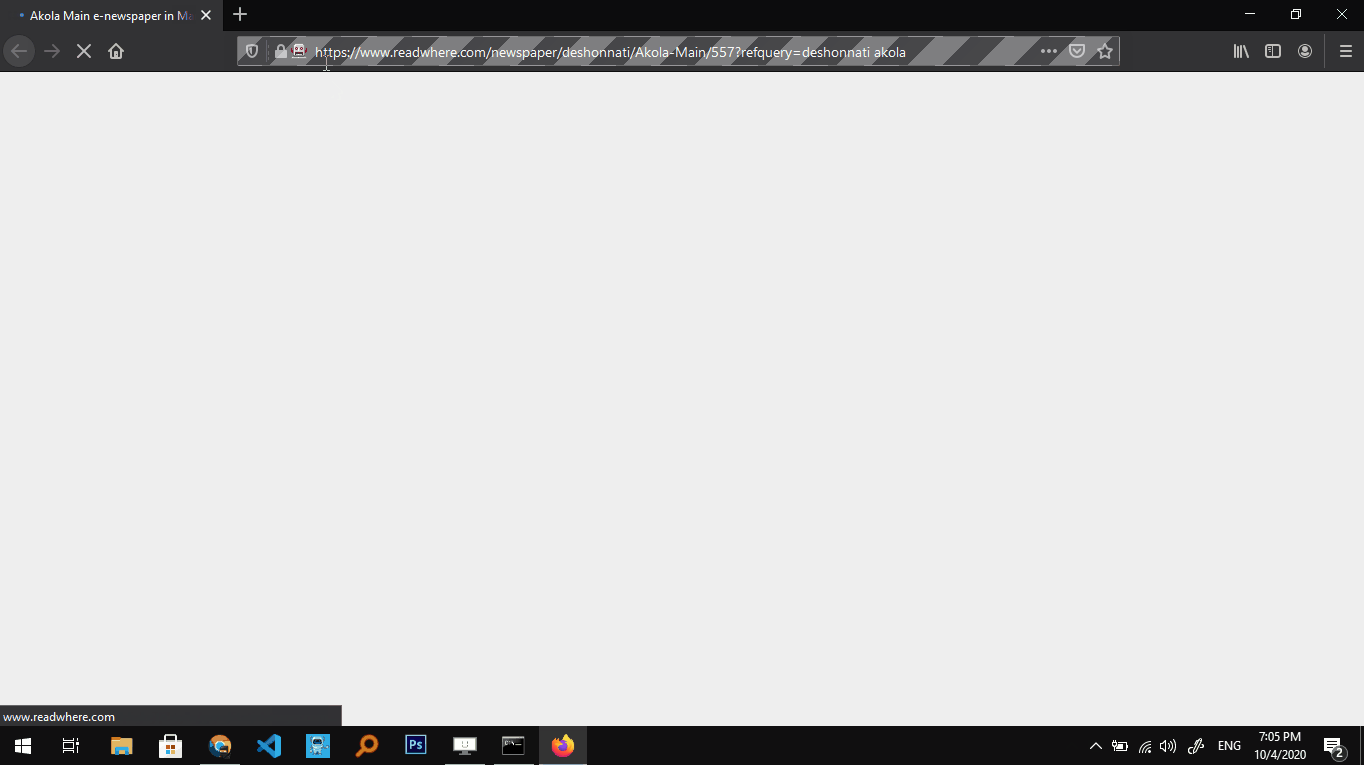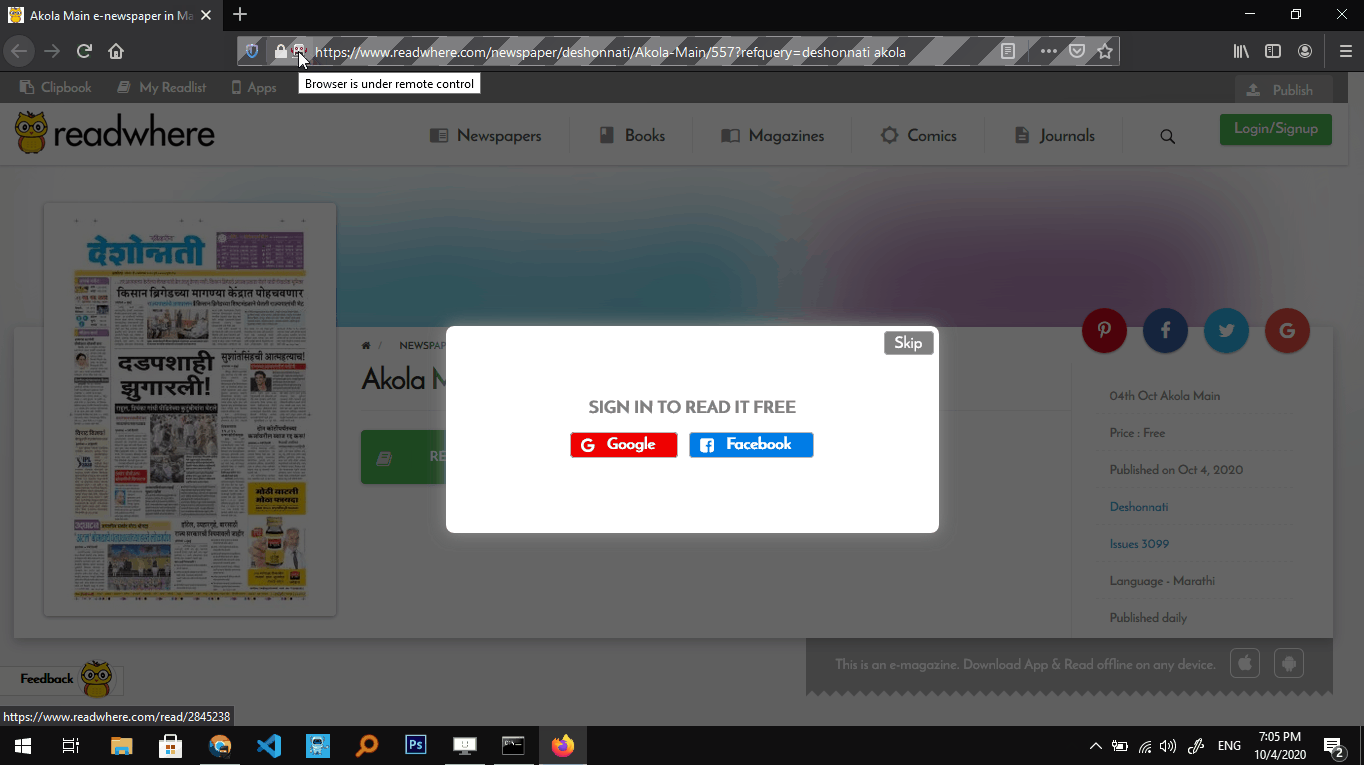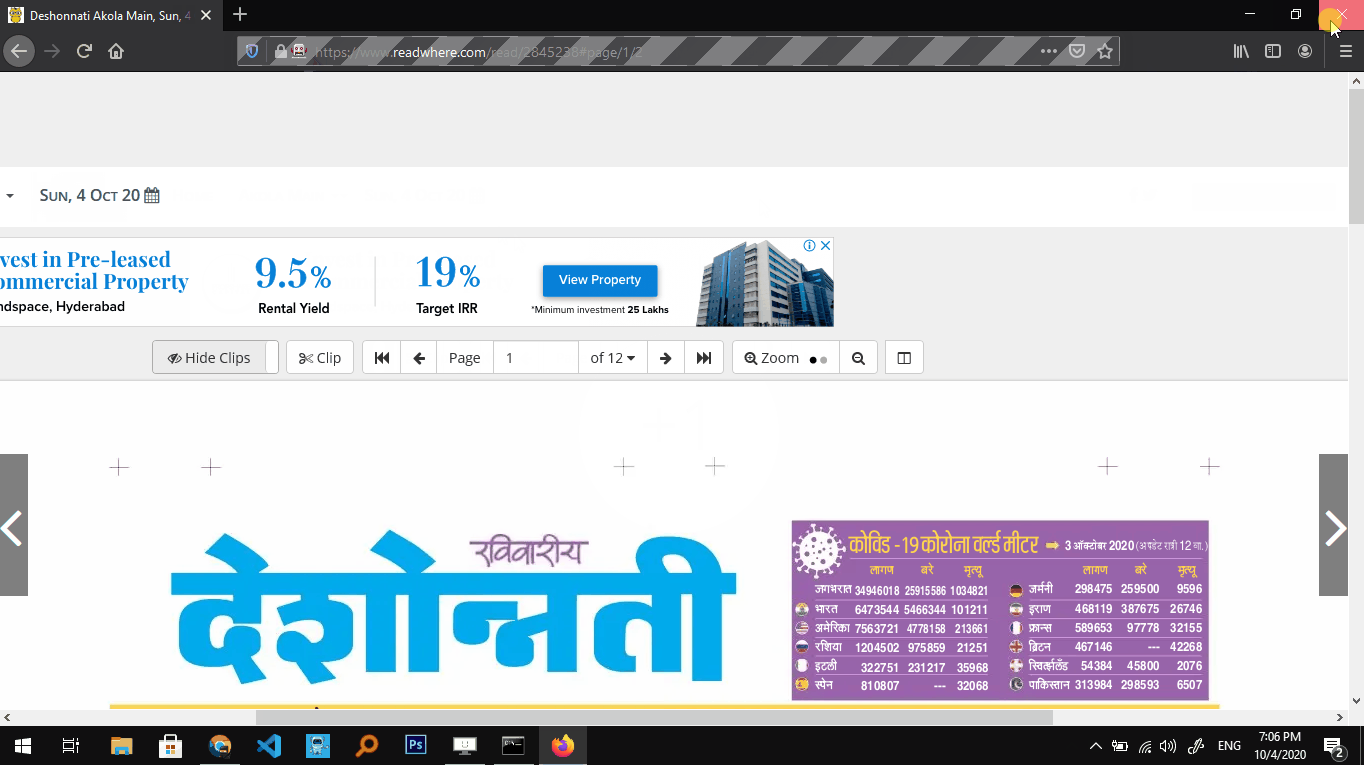
Find the complete pyclone source code on GitHub
Some other ideas you can try out.
- Change config on router ( block/unblock certain domains, Limit speed on certain devices ). You will need to supply username and password for router in input boxes(
sendkeys()can be used for that). Make sure you are not publishing these username and password in public repos. - Clock in/out i.e. time booking for employees on company website. ( Again make sure to not disclose username and password on public repos, pass it from environment variables )
Frequently Asked Questions
Do I still need to download geckodriver or chromedriver?
Not on Selenium 4.6 or newer. Selenium Manager finds or downloads a matching driver automatically.
Why does my XPath stop working after a site update?
Absolute XPaths like /html/body/div[4]/... break when the page layout changes. Prefer By.ID, By.NAME or a short CSS selector when the element has one.
How do I run the browser headless in Selenium 4?
Use options.add_argument('-headless') for Firefox or options.add_argument('--headless') for Chrome, then pass options=options to the driver.